Concept dictionary
LoRA
LoRA stands for low-rank adaptation, a technique for efficiently adjusting a model without retraining every parameter.
- Review state
- Reviewed in POC
- Freshness
- Current
- Version
- 2
Also called
- LoRA
- Low-Rank Adaptation
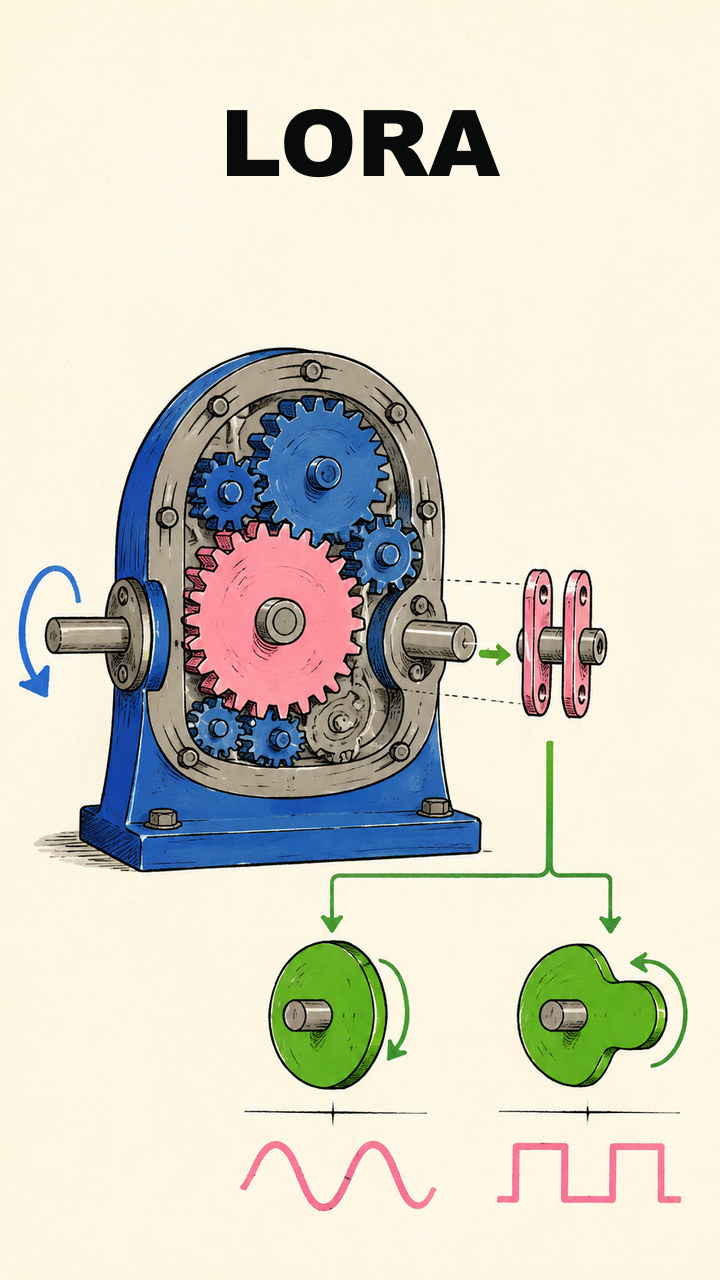
Remember it this wayFreeze the base; train a small low-rank adapter.
In plain language
LoRA, short for Low-Rank Adaptation, fine-tunes a model by training small low-rank matrices while keeping the original model weights frozen. The resulting adapter can be stored separately from the base model.
Why it matters
LoRA can reduce the compute, memory, and storage needed for adaptation. It does not remove the need to evaluate the training data, base model, adapter behavior, or deployment combination.
Example
A company adapts one base language model to several departments by training and loading a small LoRA adapter for each domain.
Common misconception
LoRA is not a new base model and does not update every original weight. Its behavior depends on both the frozen model and the trained adapter.
Related terms
Sources
- Edward Hu and colleagues, “LoRA: Low-Rank Adaptation of Large Language Models”introduces low-rank trainable matrices applied while pretrained weights remain frozen.
Learn more
- Compare [[fine-tuning|Fine-Tuning]], [[weights|Weights]], [[parameters|Parameters]], and [[supervised-fine-tuning|Supervised Fine-Tuning]] to place LoRA in the surrounding system.
- Follow the cited source material above for the method, standard, or research context behind this draft.