Concept dictionary
Supervised Fine-Tuning
SFT stands for supervised fine-tuning, a stage where a pretrained model is further trained on labeled examples to improve task-following behavior.
- Review state
- Reviewed in POC
- Freshness
- Current
- Version
- 2
Also called
- Supervised Fine-Tuning
- SFT
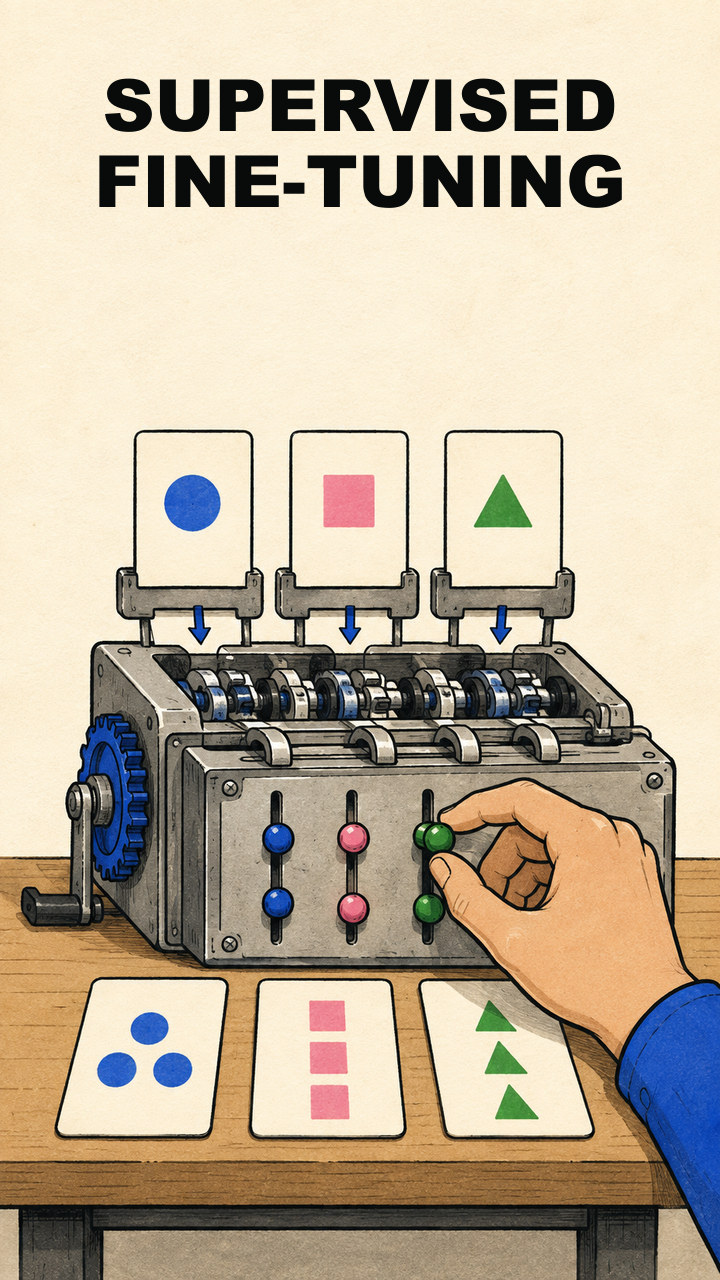
Remember it this wayShow labeled examples, then continue training the model on them.
In plain language
Supervised Fine-Tuning, or SFT, continues training a pretrained model on labeled input-output examples that demonstrate the desired task or response behavior.
Why it matters
SFT can teach format, task behavior, and domain patterns, but it reproduces the strengths and blind spots of the demonstrations. Data selection and review remain central.
Example
A pretrained language model is fine-tuned on prompts paired with carefully reviewed support answers so it learns the organization’s response style and escalation rules.
Common misconception
SFT is not the same as prompting and does not guarantee broad alignment. It changes model parameters based on a specific demonstration set.
Related terms
Sources
- Long Ouyang and colleagues, “Training Language Models to Follow Instructions with Human Feedback”documents supervised fine-tuning on human-written demonstrations as the first InstructGPT post-training stage.
Learn more
- Compare [[fine-tuning|Fine-Tuning]], [[pretraining|Pretraining]], [[supervised-learning|Supervised Learning]], and [[rlhf|RLHF]] to place Supervised Fine-Tuning in the surrounding system.
- Follow the cited source material above for the method, standard, or research context behind this draft.