Concept dictionary
Multimodal
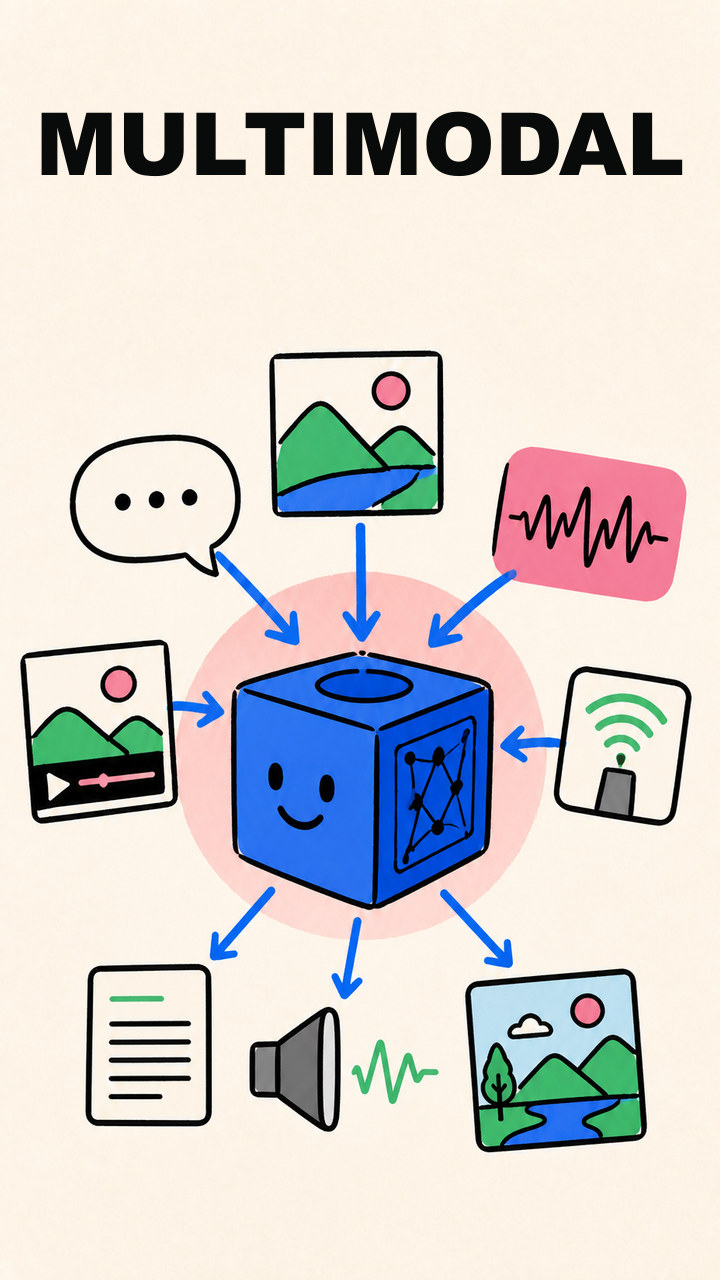
Multimodal describes a model or system that can work with more than one kind of data, such as text, images, audio, video, or sensor information.
- Review state
- Reviewed in POC
- Freshness
- Current
- Version
- 2
Also called
- Multimodal
- Multimodal AI
Remember it this wayMore than one kind of input or output is in play.
In plain language
A multimodal system may accept one type of input and produce another, or combine several types at once. The exact supported combinations and quality differ by product and model.
Why it matters
Combining modalities can make tools more useful, but it also creates new privacy, provenance, accessibility, and evaluation questions across each input and output type.
Example
A user supplies a photograph and a spoken question, and the system returns a text explanation of what appears in the image.
Common misconception
Multimodal does not mean the system handles every medium equally well or combines them with humanlike perception.
Related terms
Sources
- NIST, Adversarial Machine Learning: A Taxonomy and Terminology of Attacks and Mitigations (NIST AI 100-2 E2025)defines multimodal models as processing and relating information from multiple sensory modalities.
Learn more
- Review media lineage with [[data-provenance|Data Provenance]] and generated content with [[generative-ai|Generative AI]].