Concept dictionary
Model Distillation
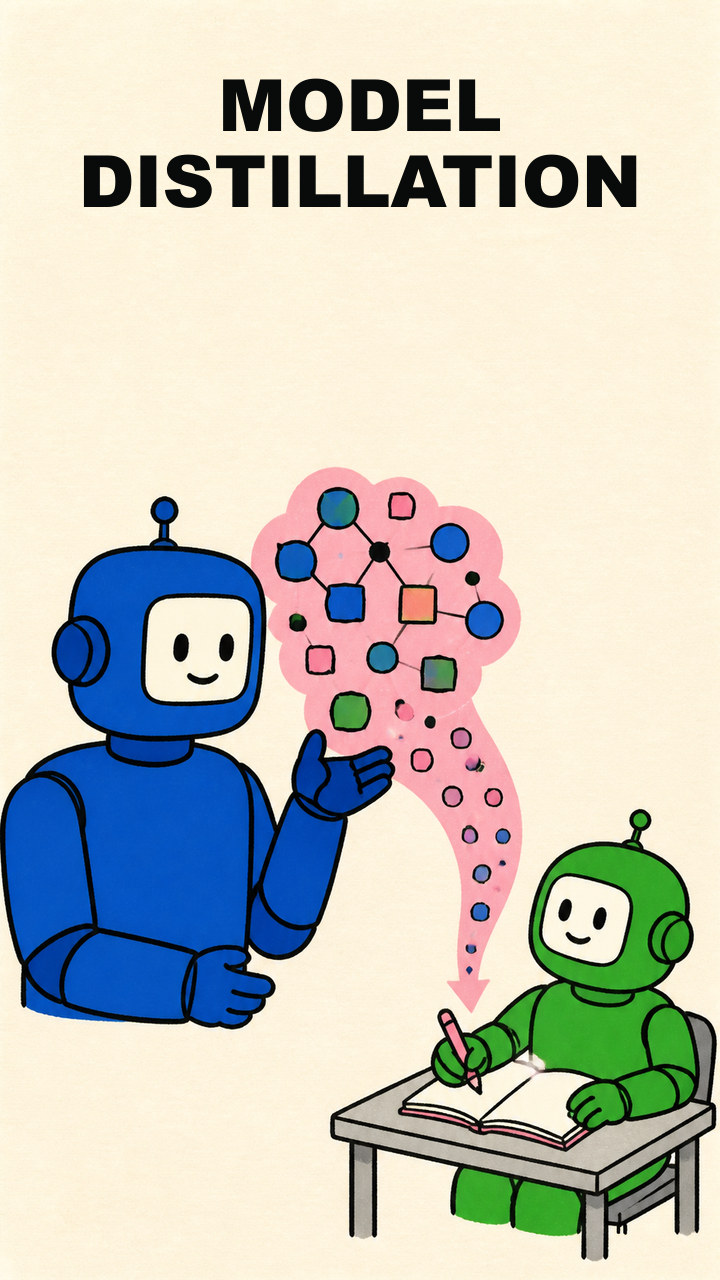
Model distillation is a training approach in which a smaller model learns to reproduce selected behavior of a larger or more capable teacher model.
- Review state
- Needs review
- Freshness
- Current
- Version
- 2
Also called
- Model Distillation
- Knowledge Distillation
Remember it this wayThe student learns selected behavior from the larger teacher.
In plain language
The smaller student model trains on outputs, probabilities, examples, or guidance produced by the teacher so it can perform useful tasks with less compute, memory, latency, or cost.
Why it matters
Distillation can make deployment practical, but the student may inherit teacher errors or lose capabilities in ways that require fresh evaluation.
Example
A company distills a large language model into a smaller model for a narrow classification task that must run on local hardware.
Common misconception
A distilled model is not simply a compressed file or guaranteed miniature copy. It is a separately trained model with its own behavior and limitations.
Related terms
Sources
- Hinton, Vinyals, and Dean, Distilling the Knowledge in a Neural Networkprimary paper describing knowledge distillation.
Learn more
- Record the teacher and training process in [[capability-provenance|Capability Provenance]].